Theo Keller · 14 September 2026
Navigating Iterative Feedback Mechanisms in Scalable Digital Infrastructure Projects
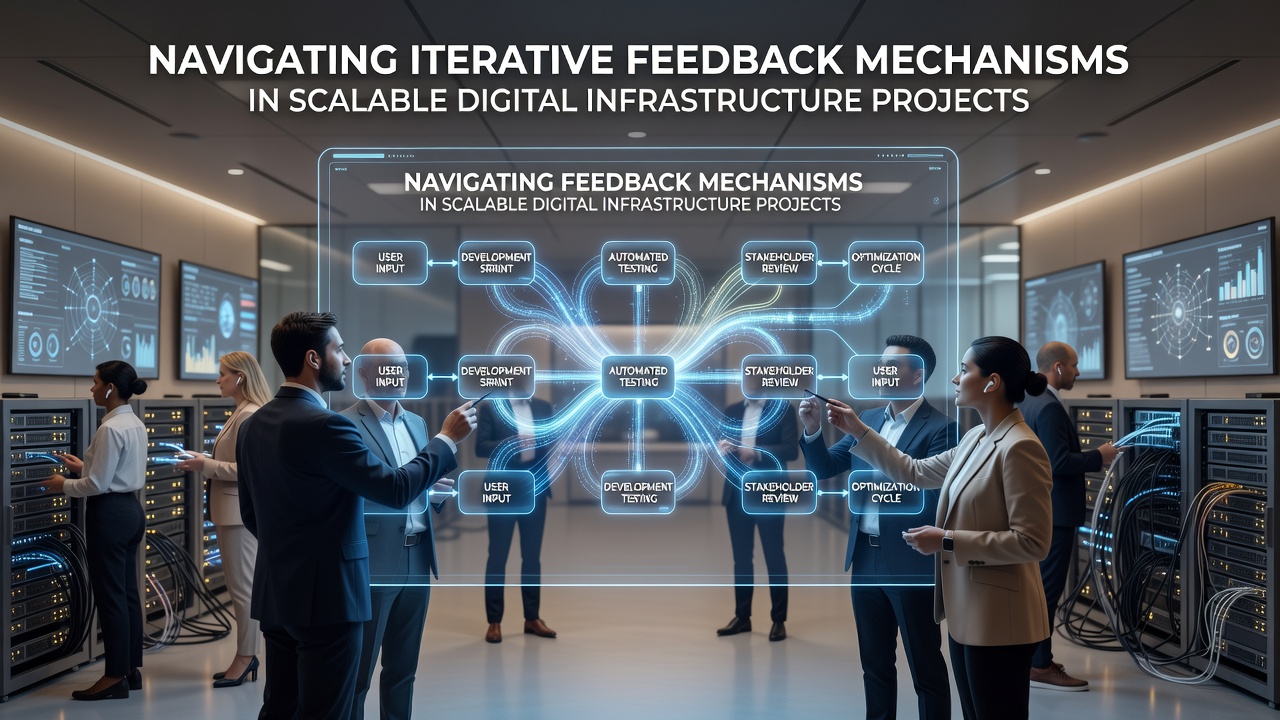
Digital infrastructure projects that expand across regions rely on iterative feedback mechanisms to adjust capacity, security protocols, and integration points as user demands shift, and these systems collect performance metrics from distributed servers, network nodes, and application layers before routing adjustments back into development cycles. Teams monitor latency spikes during peak hours while logging error rates from containerized workloads, then apply those readings to refine load balancers and database sharding strategies within the same sprint windows.
Core Components of Feedback Loops
Monitoring platforms capture real-time telemetry from edge devices and central cloud regions, then aggregate the data into dashboards that highlight bottlenecks in storage throughput or API response times, and engineers review these outputs during daily standups to prioritize patches or configuration changes. Version control repositories track every modification so that rollback options remain available when new scaling rules introduce unexpected latency in secondary zones.
Automated testing suites run after each code merge, simulating traffic loads that mirror September 2026 projections for global 5G adoption, and results feed directly into ticket systems that assign remediation tasks based on severity thresholds. This process keeps infrastructure teams aligned with evolving compliance standards from multiple regulatory bodies without halting ongoing deployments.
Challenges in Large-Scale Environments
Coordinating feedback across multi-vendor hardware creates delays when one provider's monitoring API returns incompatible data formats, forcing teams to build custom parsers that add processing overhead to already strained networks. Geographic distribution compounds the issue because latency between North American and Asia-Pacific data centers can stretch the time between anomaly detection and resolution beyond acceptable windows for financial or healthcare workloads.
Data silos emerge when separate departments maintain independent logging systems, and merging those streams requires governance frameworks that define ownership and access rights before any cross-team analysis begins. Resource contention arises when feedback-driven scaling decisions compete with scheduled maintenance windows, requiring priority matrices that weigh business impact against technical debt accumulation.
Implementation Approaches Across Regions
Organizations in the European Union integrate feedback mechanisms with directives from the European Commission on digital infrastructure resilience, embedding automated alerts that flag deviations from energy efficiency targets during expansion phases. Canadian federal projects apply similar loops to track cybersecurity metrics across provincial networks, using reports from the Communications Security Establishment to calibrate intrusion detection thresholds after each iteration.
Researchers at institutions such as those publishing through the OECD track how iterative adjustments reduce downtime in national broadband initiatives, noting that projects incorporating weekly metric reviews achieve faster recovery from regional outages compared with annual planning cycles. Teams incorporate these findings by scheduling dedicated review sessions that examine both quantitative telemetry and qualitative operator notes on recurring issues.
Tools and Metrics That Drive Adjustments
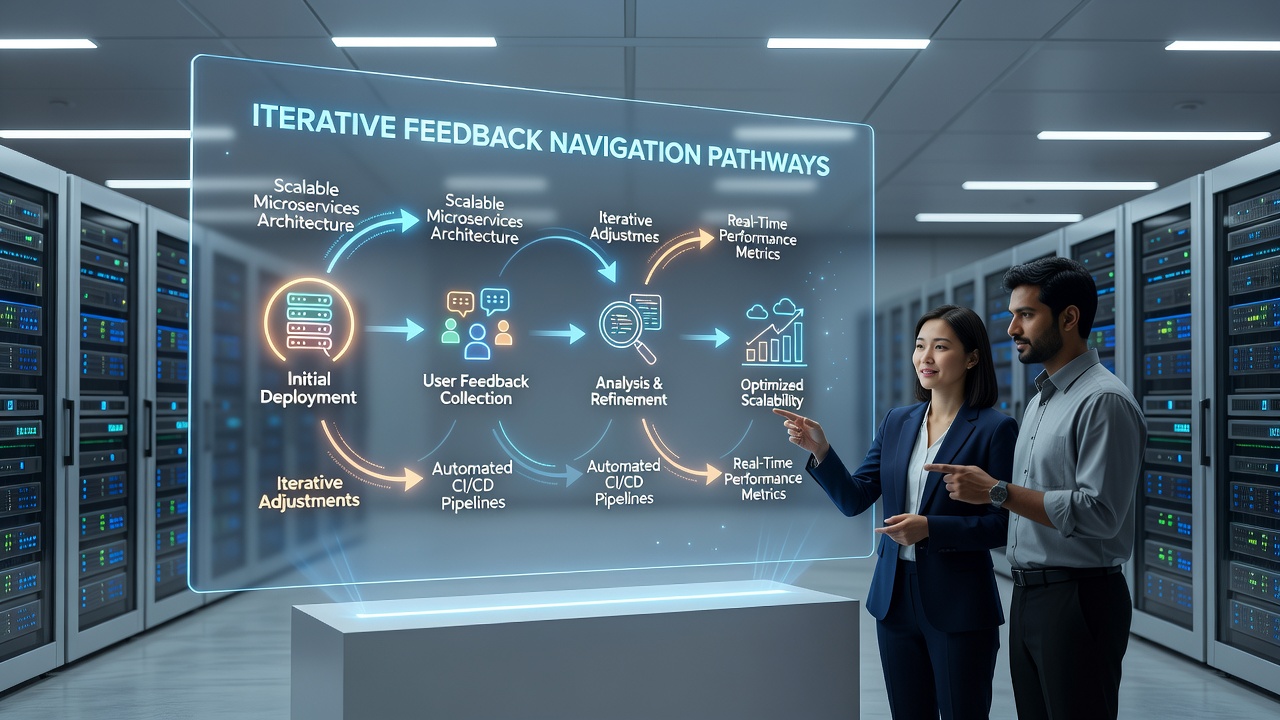
Prometheus and Grafana stacks collect time-series data on CPU utilization and packet loss rates, feeding the outputs into machine learning models that predict capacity needs two quarters ahead based on historical growth patterns. Jira and similar platforms route the resulting action items to infrastructure squads while maintaining traceability from initial observation through final deployment verification.
Key performance indicators include mean time to recovery after scaling events and the percentage of feedback items resolved within defined sprint boundaries, and these figures appear in executive summaries that justify continued investment in monitoring infrastructure. Integration with CI/CD pipelines ensures that validated changes deploy automatically once tests confirm stability across simulated multi-region scenarios.
Case Examples from Recent Deployments
One research group examining municipal smart city rollouts documented how feedback loops adjusted traffic sensor networks after initial deployments revealed underestimation of data volumes during rush hours, and subsequent iterations incorporated edge processing nodes that reduced central server load by measurable percentages. Another study focused on university research networks showed that incorporating operator feedback on authentication delays led to protocol refinements that improved login success rates across distributed campuses.
Conclusion
Iterative feedback mechanisms continue to shape how digital infrastructure projects scale while maintaining reliability across expanding user bases and regulatory landscapes, and the integration of telemetry-driven decisions with cross-regional coordination remains central to managing complexity. Data from ongoing deployments in 2026 indicate that organizations refining these loops achieve tighter alignment between projected capacity and actual demand patterns, supporting sustained growth without proportional increases in operational overhead.